01
Case-insensitive
Capitalised and lowercase forms of a word are merged into one entry.
Start typing to search 227 tools.
List every distinct word in a text once, in first-seen order, with a total count. Case-insensitive and Unicode-aware.
The unique word finder reads a piece of text and returns every distinct word exactly once. Words are compared in lowercase, so “The”, “the” and “THE” count as one word. The list keeps the order in which each word first appeared, and the status line shows how many distinct words were found.
It is useful for checking the vocabulary of an article, preparing a word list from a transcript, spotting how varied a draft is, or collecting terms for a glossary or keyword review. If you also need to know how often each word occurs, use the Word Frequency Counter instead.
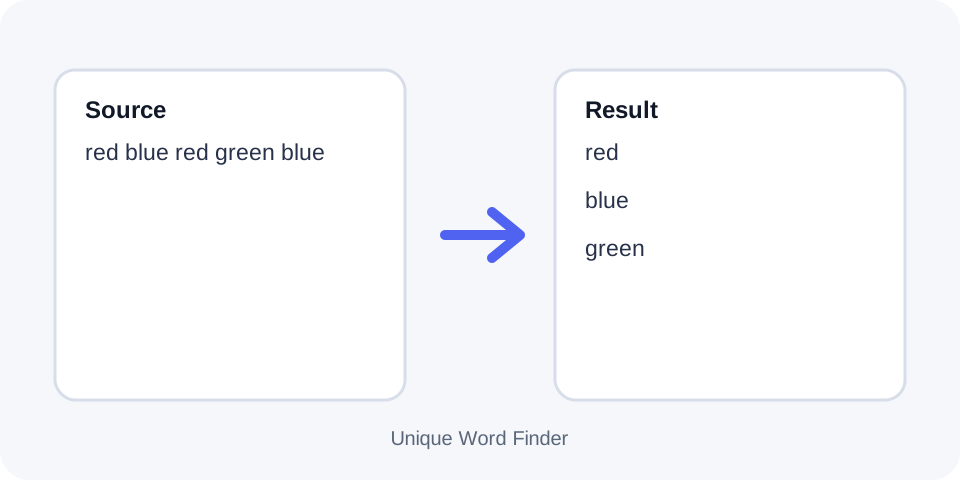
Focused controls, predictable output, and a workflow designed around this exact transformation.
Capitalised and lowercase forms of a word are merged into one entry.
The list follows the text, so you can see where new vocabulary appears.
The output pastes cleanly into spreadsheets and other tools.
The text is processed in your browser while you work with it.
Practical details about input, output, privacy, limits, and the best way to use this tool.
A word is a run of letters or digits, optionally joined by an inner apostrophe or hyphen, such as “don’t” or “well-known”. Other punctuation is ignored.
No. All text is lowercased before comparison, so the output list is lowercase.
No. It lists each word once. For counts per word, use the Word Frequency Counter.
No. The tool compares exact word forms and does not do stemming or lemmatization, so “run”, “runs” and “running” are three entries.
Yes. Sequences of digits such as 2024 are listed like any other word.
Yes. Letters from any script are recognised, and lowercasing follows Unicode rules.
A typographic apostrophe (’) is recognised inside a word but is removed from the output, so “don’t” appears as “dont”. A straight apostrophe (') is kept. Replace curly apostrophes first if you need exact forms.
The tool lowercases the input, extracts words, strips any characters that are not letters, digits, apostrophes or hyphens, and keeps the first occurrence of each. The result is a plain list and a count in the status line. Nothing is sorted, so the list reads in the same order as your text.
The number of distinct words relative to the total number of words is a rough measure of vocabulary variety. A short product description repeats its key terms on purpose, while a long essay should introduce new words steadily. Use the count as a hint, not as a quality score. Compare the total from the Word Counter with the distinct count here to see how repetitive a text is.
The finder compares exact word forms, so inflections count separately. Typographic apostrophes are dropped, and abbreviations with dots, such as “e.g.”, become “e” and “g”. To remove repeated words from the text itself while keeping the rest, use Remove Duplicate Words.
Word Frequency Counter shows how often each word is used. Word Counter reports words, characters, sentences and reading time.